 QAcart Signals
Never ship a broken app again.
Your AI agents write code all day. QA Agents spin up for every pull request, test it against your real app, and answer GO or NO-GO, with evidence, before anything reaches your users.
- ~2 sto spin up a QA Agent
- ~1 minfrom PR to verdict
- ~$0.15per request
- $0when idle
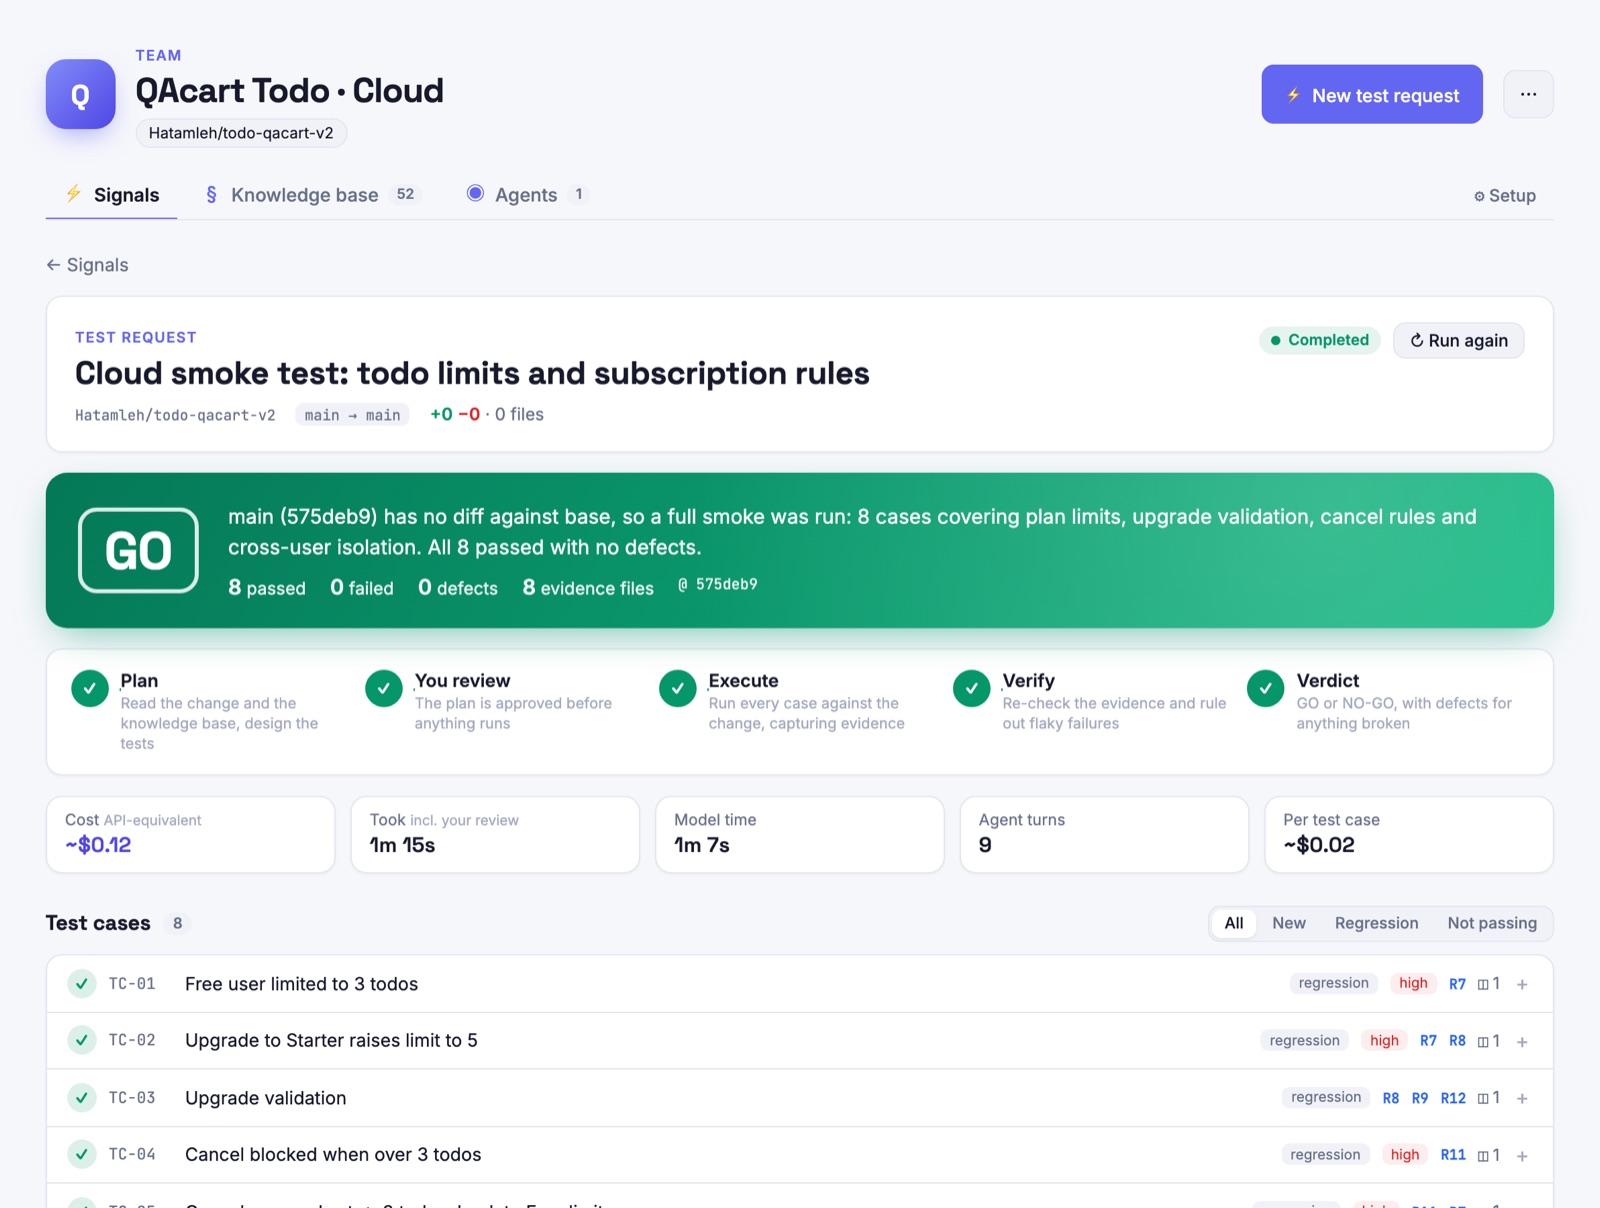
Agents ship code faster than anyone can check it.
Nobody checks the product: the limits, the permissions, the flows your users actually take.
New behaviour from an agent rarely comes with new tests, and regressions slip through.
Always-on staging and manual QA don't scale to a hundred PRs a day.
QA Agents give every change a tester who knows your product, runs your real app, and leaves proof.
From pull request to verdict, on the fly.
A QA Agent exists only for the life of a request. It appears when a PR lands, tests, decides, and disappears.
Your coding agent pushes a change
A fresh sandbox from your environment snapshot, in ~2 s
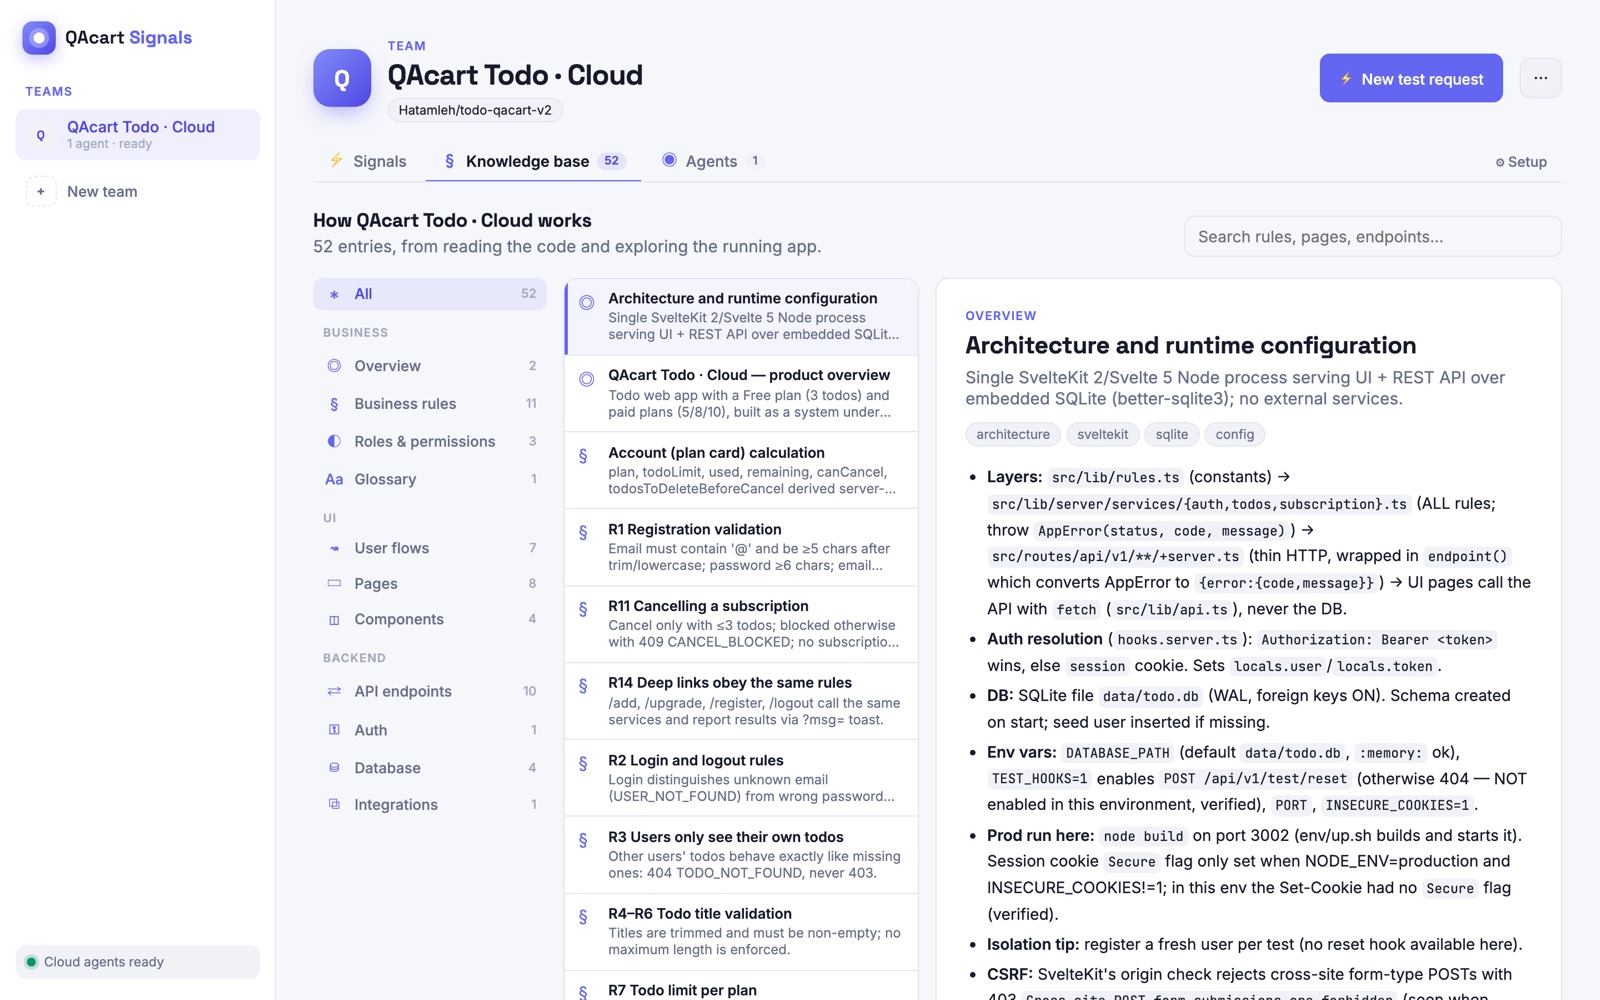
New cases for the change, regression from the knowledge base
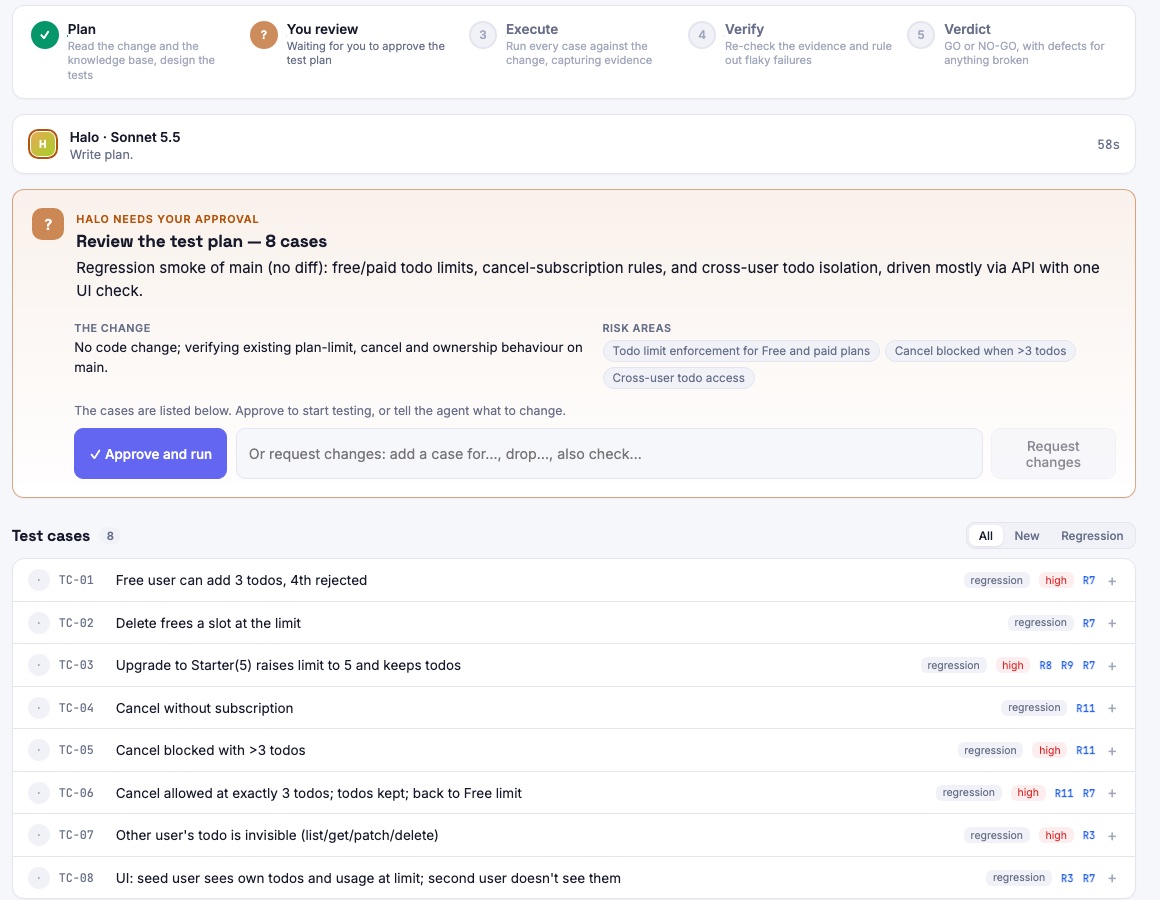
Or a QA-manager agent reviews the plan
UI, APIs and data, with screenshots and responses
Re-checks evidence, re-runs failures to rule out flakes
A verdict, and defects with reproduction steps
The sandbox is deleted. Nothing idles, nothing to pay
Pay per request. Never for idle machines.
A QA environment that waits around all day costs money all day. QA Agents only exist while a PR is being tested.
Based on measured runs: an 8-case test request took about 1 minute of model time and $0.12–0.20 of Claude usage. Bigger changes cost more. Signals itself is free during the preview.
See exactly what your QA Agents did.
A clear GO or NO-GO on every change
- Five visible stages from plan to verdict
- Cost, time and turns of every run
- Every case tied to the business rule it protects
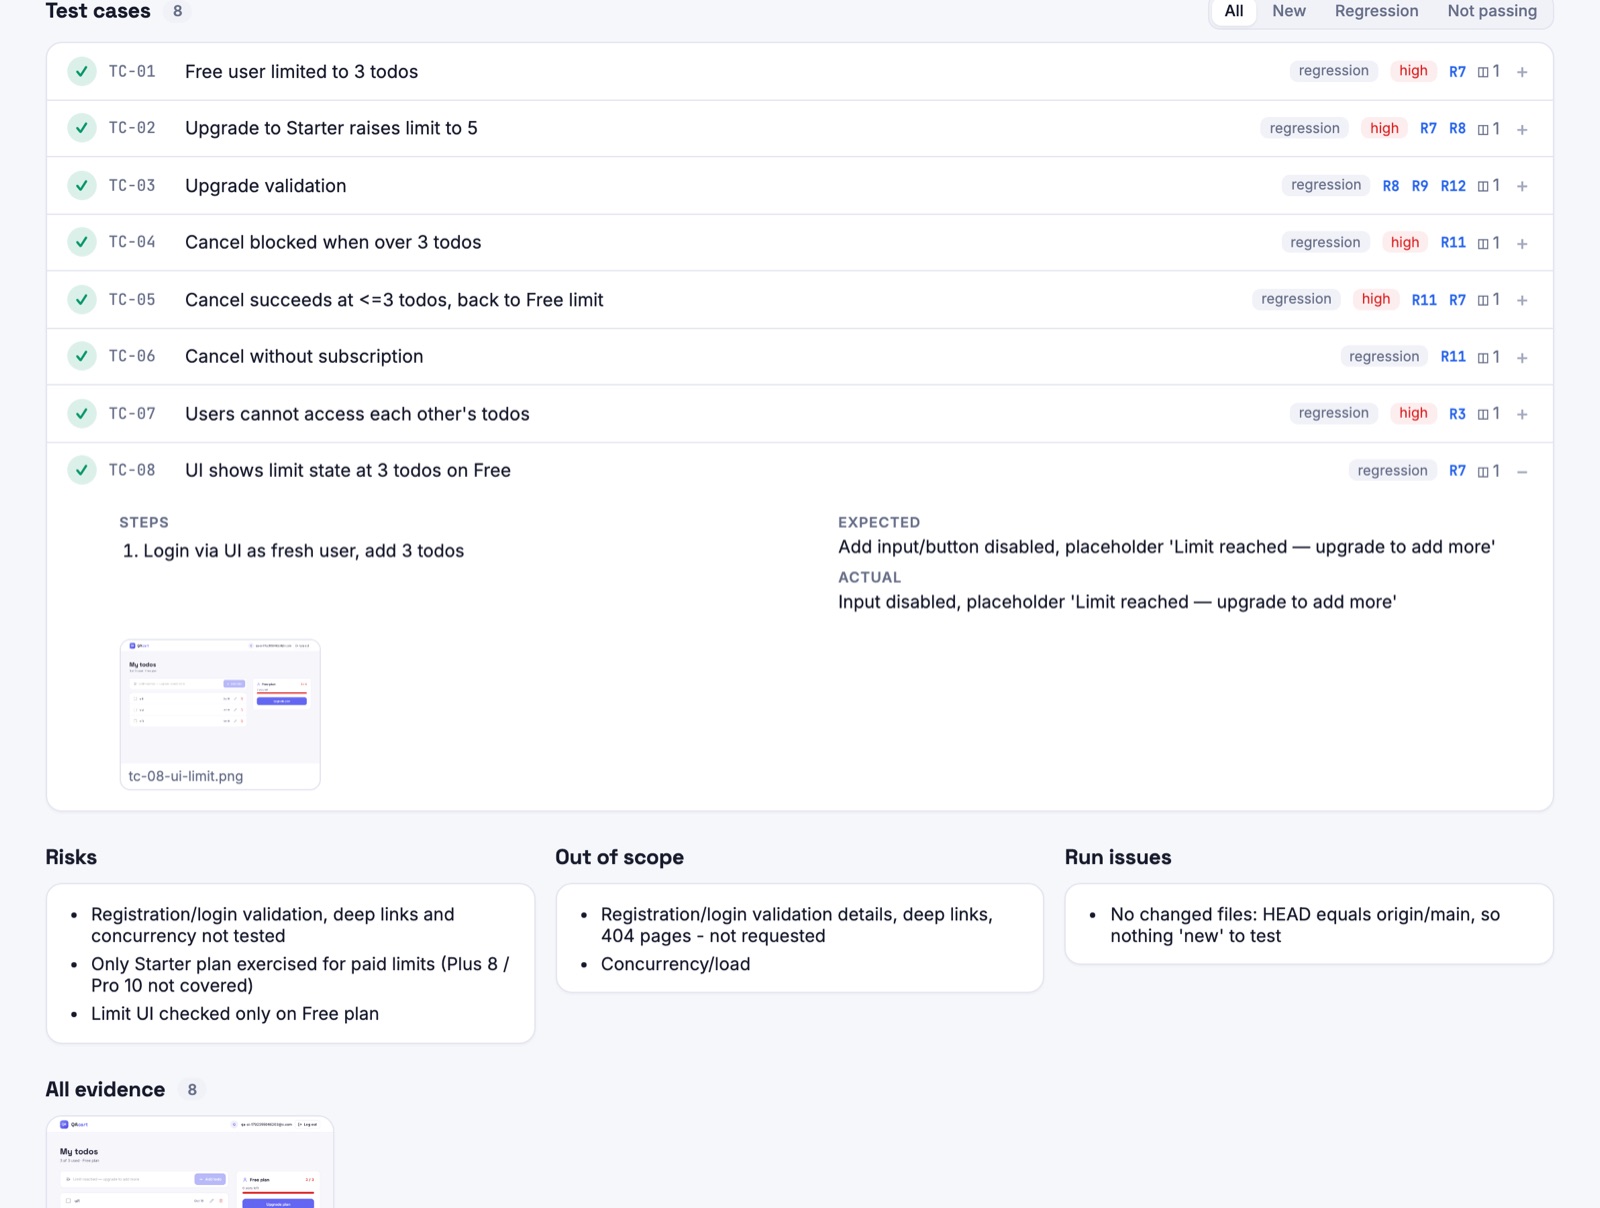
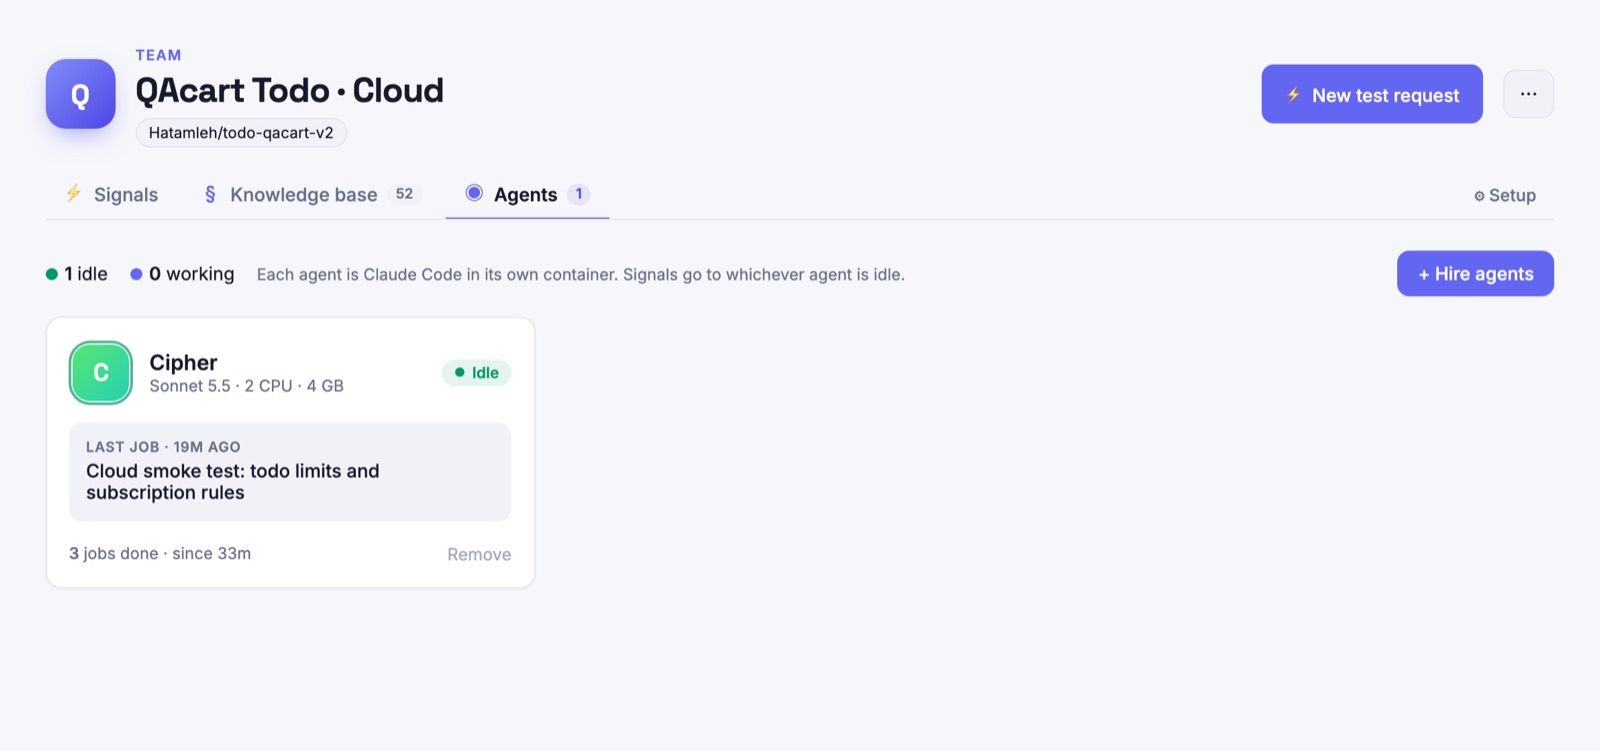
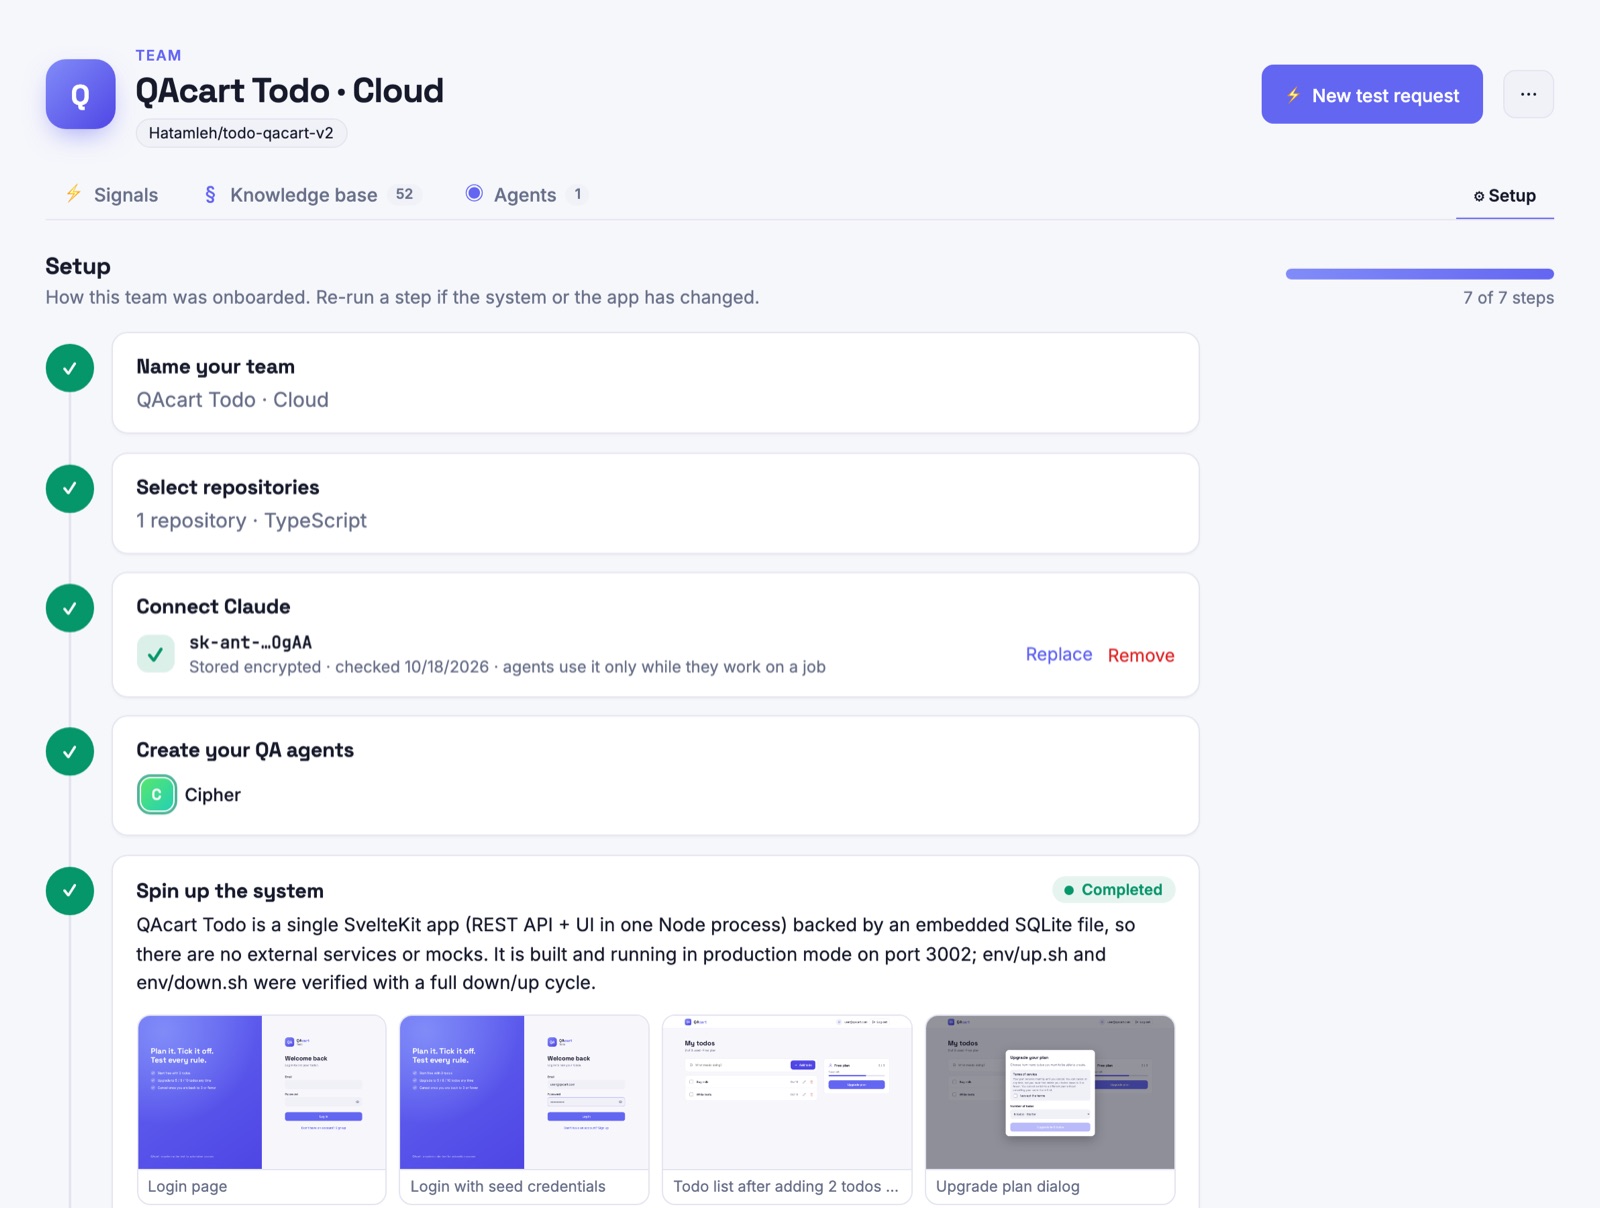
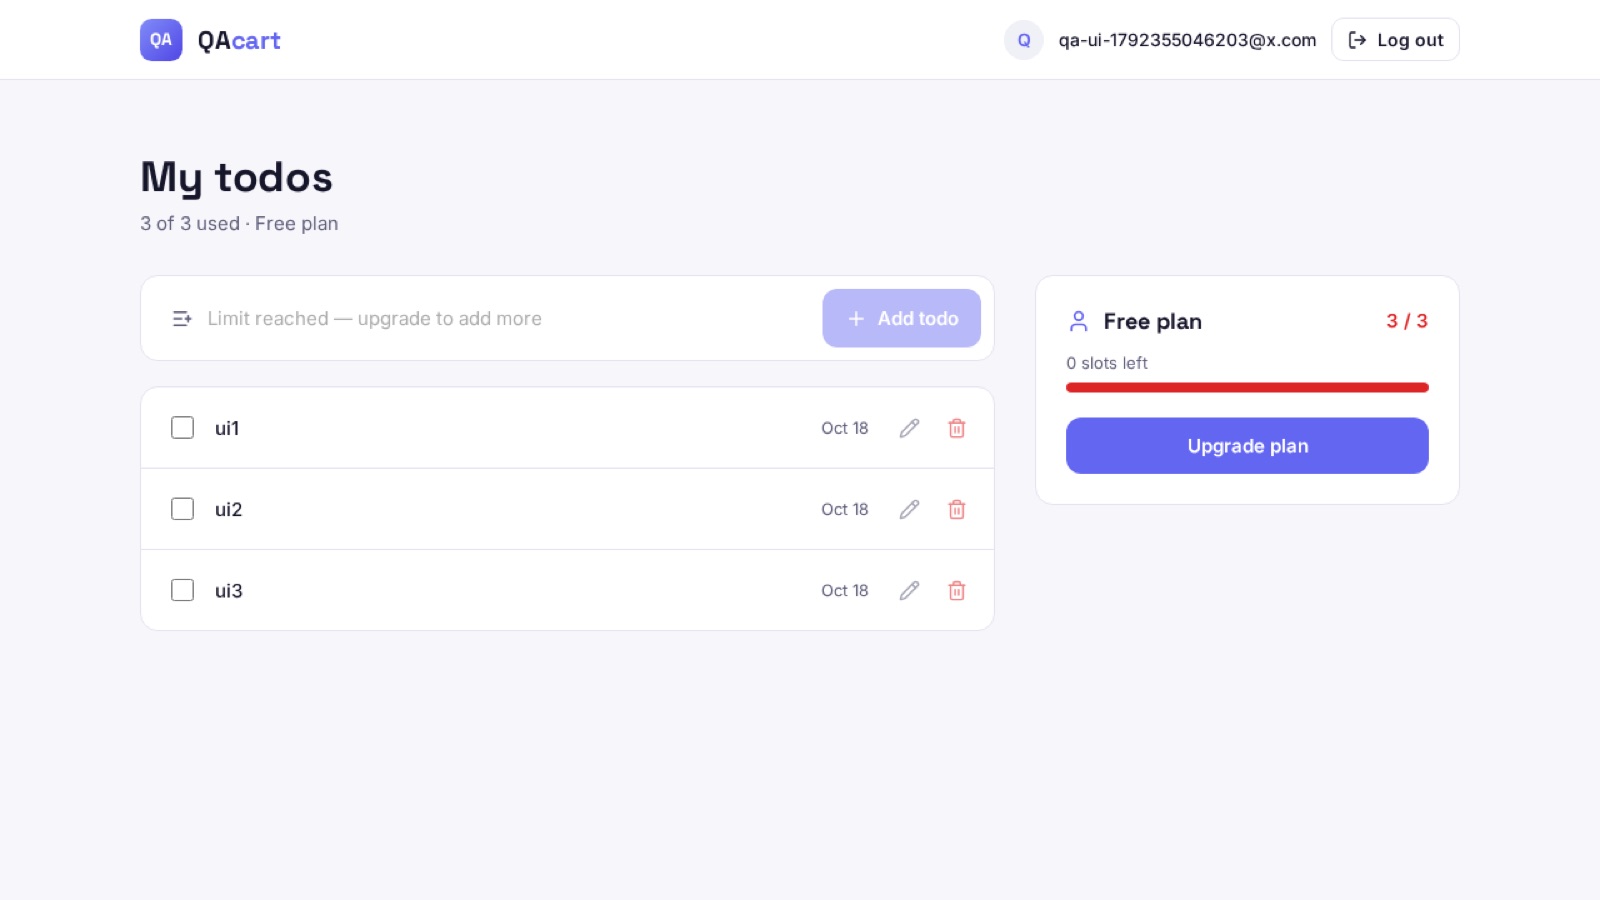
Every claim comes with a screenshot.
This is what a QA Agent actually saw while checking that a Free user is stopped at 3 todos. A pass needs proof too.
We provide QA Agents, not AI.
Your code and prompts go through your own Claude account, under your data terms. We never resell or mark up model usage.
- Your key, encrypted. Stored in an encrypted vault and handed only to the sandbox running your request.
- One sandbox per request. Fresh every time, deleted afterwards, in the EU.
- Mocks, not real services. Payments, email and OAuth are never called for real during tests.
- Your cloud, your contract. Use Claude through AWS Bedrock, Google Vertex AI or Microsoft Foundry.
- Your network, on request. Runners inside your own infrastructure are on the enterprise roadmap.
Questions, answered.
Claude: Opus for planning and review, Sonnet for exploring and executing, Haiku for simple checks. You bring your own key from Anthropic, or use Claude through your AWS Bedrock, Google Vertex AI or Microsoft Foundry account.
 Private preview
Put QA Agents on every pull request.
We're onboarding a small number of teams that build with AI coding agents. Tell us about yours and we'll send an invite.
- Free during the preview
- Guided onboarding of your first project
- You only pay Anthropic for model usage, per request